 The Story MarketMunich, Germany (remote)
NLP · topic modelling
German News Topic Discovery
A month of German news, organised into topics.
- 3,283German articles from one month of news (December 2021)
- 40topics found without fixing their number in advance
- 3document representations benchmarked: TF-IDF, Doc2Vec, BERT
Overview
The problem
A media-intelligence company needs to know what the press is writing about, in German, every month. Thousands of articles arrive without labels, new stories appear constantly, and keyword lists miss them.
What was missing
Bag-of-words representations count words, not meaning, and the number of topics in a month of news is not known in advance. The approach had to work in German, find the number of topics by itself and keep uncertain articles apart rather than forcing them into a topic.
Architecture
Swipe to see the whole diagram →
Swipe to see the whole diagram →
Technical details
- Embeddings: sentence-transformers distiluse-base-multilingual-cased (DistilBERT, mean pooling, dense 768 → 512 with tanh; inputs truncated to 128 tokens).
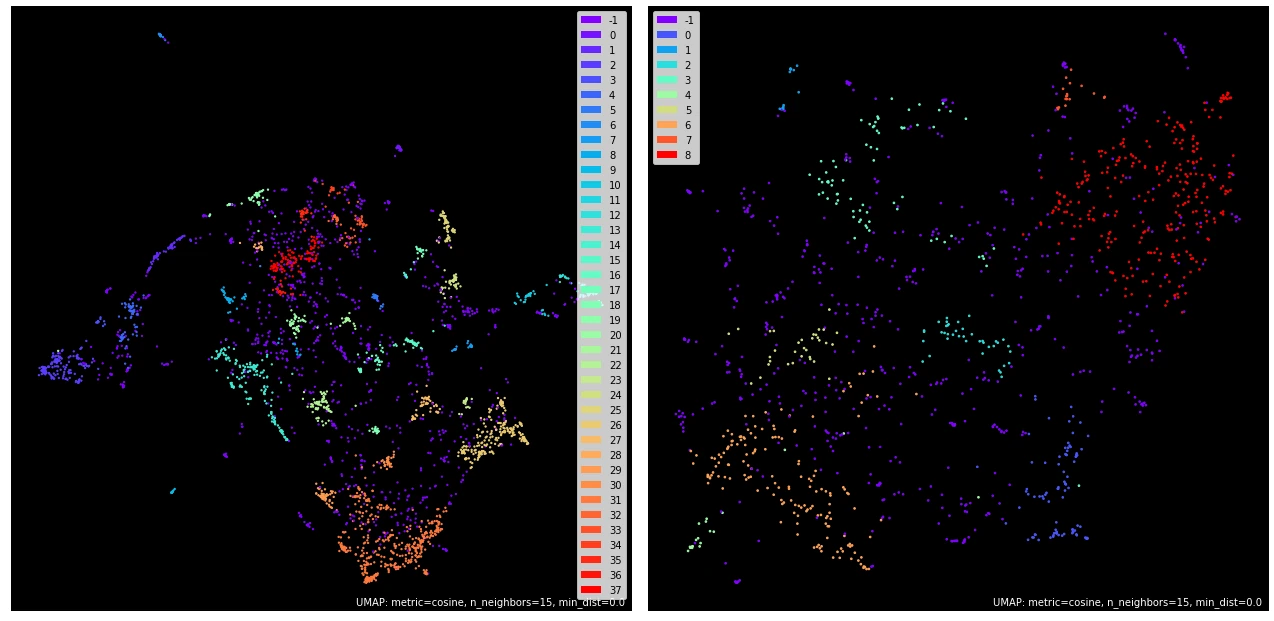
- UMAP to 5 dimensions (cosine, 15 neighbours) before clustering; a separate 2-D UMAP for the maps.
- HDBSCAN with minimum cluster size 15 and excess-of-mass selection; unassigned articles keep the label −1.
- Class-based TF-IDF: all articles of a topic are joined into one document, n-grams of length 2–3, German and English stop words plus a custom list.
- Topic merging: the smallest topic is merged into its most similar topic (cosine on c-TF-IDF), 20 rounds. Outliers are re-embedded and re-clustered; a new topic joins an existing one when the cosine similarity of their top words exceeds 0.4.
What I built
- 01
Data acquisition
Targeted scraping of major German press sources, with article text and 19 metadata fields (title, author, agency, dates, category, keywords, paywall status and more).
- 02
Representation benchmark
TF-IDF, Doc2Vec and pretrained BERT-based document embeddings compared for German news.
- 03
Topic pipeline
Multilingual Sentence-BERT embeddings, UMAP reduction, HDBSCAN clustering and class-based TF-IDF on bi- and tri-grams, with topic merging and re-clustering of outliers.
- 04
Entities
A named-entity recognition module that pulls people, organisations and places out of unstructured articles for client-facing analytics.
Main results
| Topic | Articles | Top n-grams |
|---|---|---|
| COVID-19 | 418 | omikron variante · covid 19 · bund länder |
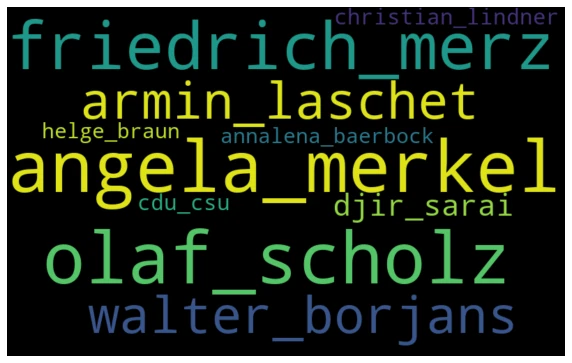
| German federal politics | 211 | olaf scholz · angela merkel · friedrich merz |
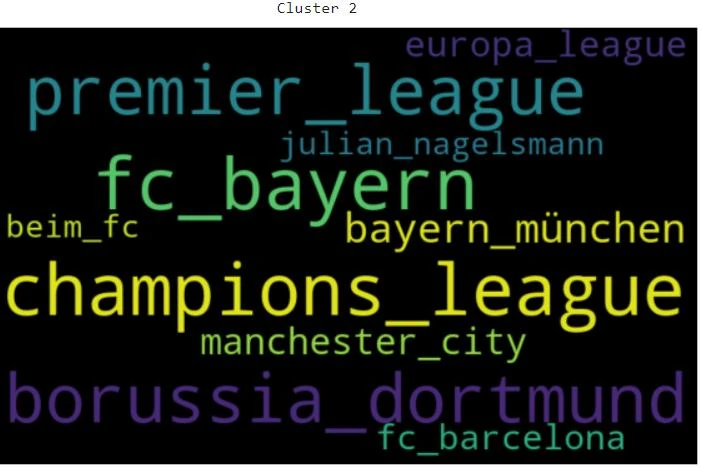
| Football | 177 | champions league · fc bayern · premier league |
| UK politics | 166 | boris johnson · downing street |
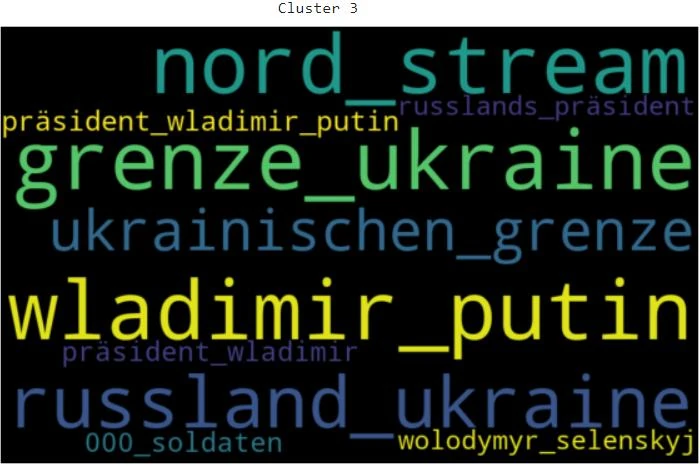
Qualitative results
Limits and next steps
UMAP is stochastic, so topics vary between runs; about a third of the articles were unassigned after the first pass; the encoder reads only the first 128 tokens of each article; evaluation was qualitative.
Beyond this project
Unsupervised organisation of any large, unlabelled text stream: support tickets, reviews, reports, scientific literature.
Contact
Interested in the work?
I'm looking for AI research engineer roles in computer vision and video understanding, ideally in sports analytics, though not only. Ready to start a new journey.
Paris, France