 Fédération Française de Tennis
 Efrei Research LabParis, France
WhenVideo understanding
TAL4Tennis
- 65.82average mAP on TenniSet, 11 classes; next best ActionFormer 62.38
- 26.18mAP at tIoU 0.9 on held-out Roland-Garros clay; ActionFormer 21.84
- 91.89frame-level Macro-F1 on the held-out set, highest of all methods
Overview
The problem
A tennis broadcast is a continuous stream: serves and exchanges alternate with replays, pauses, crowd shots and camera changes that show the same court and players. Court registration, tracking and stroke recognition are only meaningful on the in-play portions, yet those portions are usually isolated outside the learned model, by audio-visual heuristics, score-change rules or manual cutting. A missed boundary or an included replay then propagates into every downstream task.
What was missing
Racket-sport methods recognise strokes or events inside clips that already contain a rally, leaving the phase structure of the raw stream to preprocessing. Transformer localisers model long context with attention whose cost grows quadratically with sequence length, and ActionFormer restricts it to local windows. State-space models capture long-range context at linear cost, but in sports video they had mainly been applied to per-frame problems such as tracking.
Architecture
Swipe to see the whole diagram →
Technical details
- Frozen VideoMAE V2-g features: 16-frame snippets, stride 2, one 1,408-d descriptor per snippet, precomputed once and reused across epochs.
- A masked 1-D convolution embedding, a DBM stem and five DBM blocks with temporal max-pooling form a six-level pyramid. Each Decomposed Bidirectional Mamba block scans forward and backward with shared weights.
- An anchor-free point generator assigns scale-aware regression ranges; centre sampling keeps positives away from ambiguous phase edges.
- Classification: sigmoid focal loss (α = 0.25, γ = 2). Regression: one-dimensional Distance-IoU on left/right offsets. EMA of weights (0.999); 85 epochs including 5 of warm-up.
- Inference: score threshold 0.001, top 2,000 candidates per level, class-wise Soft-NMS (σ = 0.5), at most 200 segments per video.
- Ablations (TenniSet, 3 classes, average mAP): Mamba 72.32 vs Transformer 71.05 vs convolution 70.82; Soft-NMS 72.32 vs hard NMS 71.88 vs none 56.83.
What I built
- 01
Phase localisation as a learning problem
Extracting in-play sequences from continuous broadcasts is formulated as learned temporal localisation, with no externally engineered filtering.
- 02
Sequence-level context at fine resolution
Point-based boundary regression is conditioned on bidirectional Mamba scans over the whole sequence, at every level of the temporal pyramid.
- 03
An evaluation protocol for racket sports
Multi-threshold localisation benchmarking with boundary-precision diagnostics, held-out clay-court transfer without adaptation, and F³Set event detection.
Main results
| Method | tIoU ↑ | |||||
|---|---|---|---|---|---|---|
| 0.1 | 0.3 | 0.5 | 0.7 | 0.9 | Avg | |
| TemporalMaxer | 71.64 | 71.13 | 69.75 | 59.80 | 12.43 | 56.95 |
| TriDet | 75.52 | 74.79 | 73.73 | 63.91 | 15.72 | 60.73 |
| DyFADet | 75.78 | 75.35 | 74.17 | 63.91 | 14.78 | 60.80 |
| ActionFormer | 76.77 | 76.23 | 74.94 | 67.28 | 16.69 | 62.38 |
| TAL4Tennis (Ours) | 80.80 | 80.25 | 79.00 | 69.53 | 19.51 | 65.82 |
| Method | TenniSet Split 2 – tIoU ↑ | French Open Test – tIoU ↑ | ||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 0.1 | 0.3 | 0.5 | 0.7 | 0.9 | Avg | 0.1 | 0.3 | 0.5 | 0.7 | 0.9 | Avg | |
| TemporalMaxer | 87.96 | 86.30 | 82.59 | 69.21 | 15.52 | 68.31 | 69.78 | 59.17 | 54.00 | 39.89 | 5.94 | 45.75 |
| DyFADet | 89.46 | 88.38 | 83.86 | 72.28 | 21.22 | 71.04 | 69.53 | 62.08 | 59.02 | 50.07 | 18.14 | 51.77 |
| TriDet | 89.38 | 88.03 | 83.43 | 72.60 | 22.64 | 71.22 | 70.52 | 60.99 | 57.50 | 50.04 | 19.78 | 51.77 |
| ActionFormer | 90.47 | 89.11 | 83.98 | 72.10 | 23.83 | 71.90 | 69.23 | 61.80 | 59.92 | 51.51 | 21.84 | 52.86 |
| TAL4Tennis (Ours) | 90.96 | 89.70 | 83.69 | 73.56 | 23.71 | 72.32 | 69.50 | 61.64 | 58.78 | 52.57 | 26.18 | 53.73 |
| Temporal tolerance | Method | F³Set (G-high) | F³Set (G-mid) | F³Set (G-low) | ||||||
|---|---|---|---|---|---|---|---|---|---|---|
| F1-evt | F1-elm | Edit | F1-evt | F1-elm | Edit | F1-evt | F1-elm | Edit | ||
| ±2 frames | ActionFormer | 6.61 | 37.01 | 36.77 | 9.78 | 38.12 | 45.83 | 27.59 | 46.77 | 58.08 |
| TriDet | 7.40 | 39.11 | 34.49 | 11.49 | 40.81 | 45.17 | 26.56 | 48.18 | 52.44 | |
| TemporalMaxer | 3.22 | 31.77 | 24.77 | 6.34 | 33.87 | 37.50 | 18.32 | 42.21 | 45.01 | |
| DyFADet | 4.56 | 33.40 | 27.65 | 7.82 | 35.44 | 39.28 | 20.72 | 43.11 | 47.09 | |
| TAL4Tennis (Ours) | 8.51 | 40.89 | 40.69 | 12.06 | 42.11 | 49.77 | 30.89 | 50.70 | 60.94 | |
| ±4 frames | ActionFormer | 10.37 | 57.83 | 36.77 | 15.20 | 59.35 | 45.83 | 43.26 | 73.15 | 58.08 |
| TriDet | 10.42 | 56.56 | 34.49 | 16.48 | 59.13 | 45.17 | 38.08 | 69.93 | 52.44 | |
| TemporalMaxer | 5.21 | 47.95 | 24.77 | 9.97 | 51.21 | 37.50 | 28.12 | 64.34 | 45.01 | |
| DyFADet | 6.91 | 49.85 | 27.65 | 11.88 | 52.91 | 39.28 | 30.88 | 64.59 | 47.09 | |
| TAL4Tennis (Ours) | 12.82 | 61.80 | 40.69 | 18.09 | 63.64 | 49.77 | 46.97 | 75.55 | 60.94 | |
Qualitative results
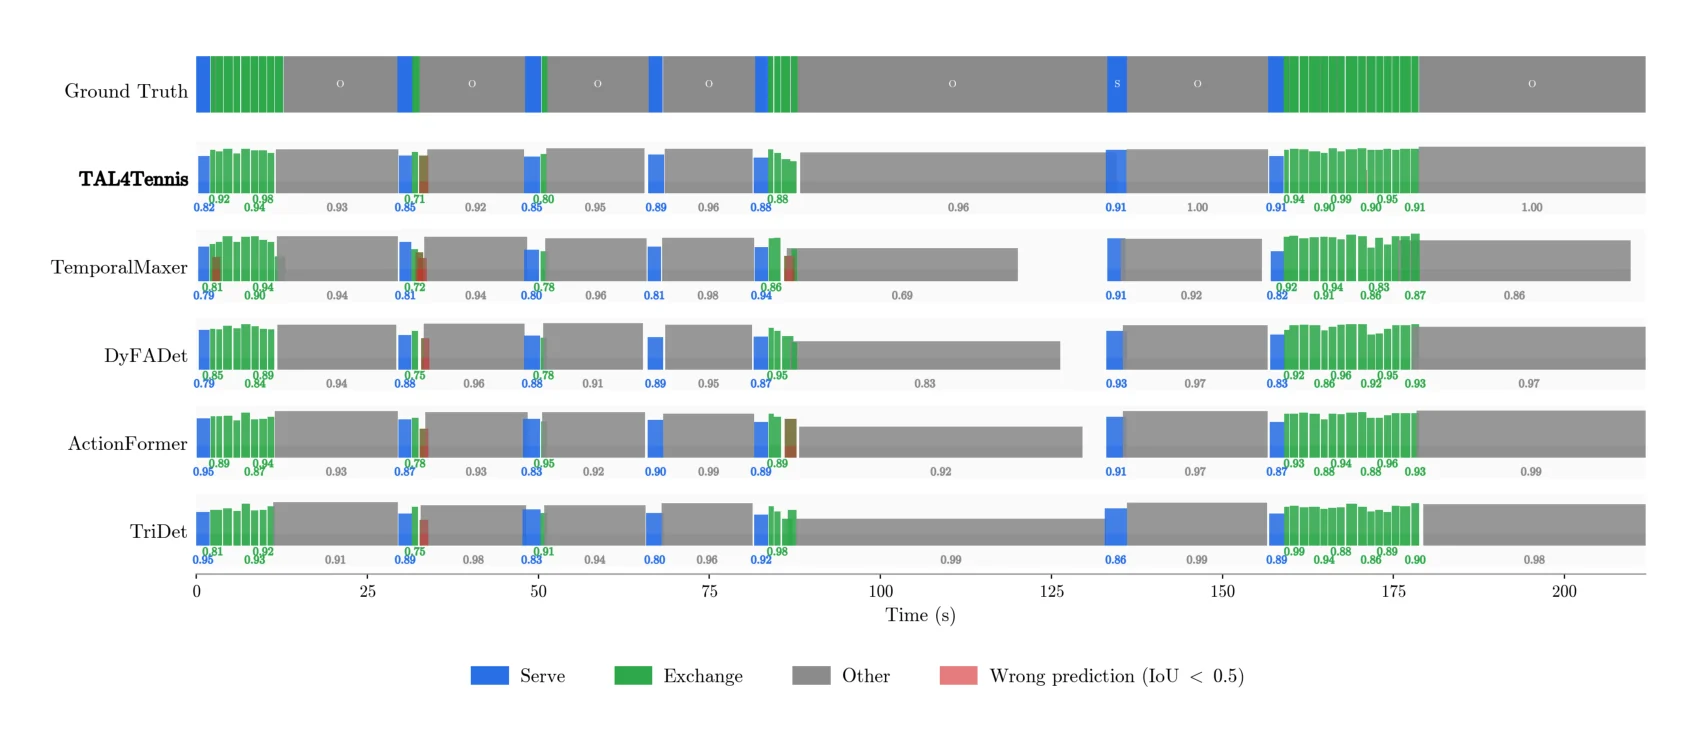
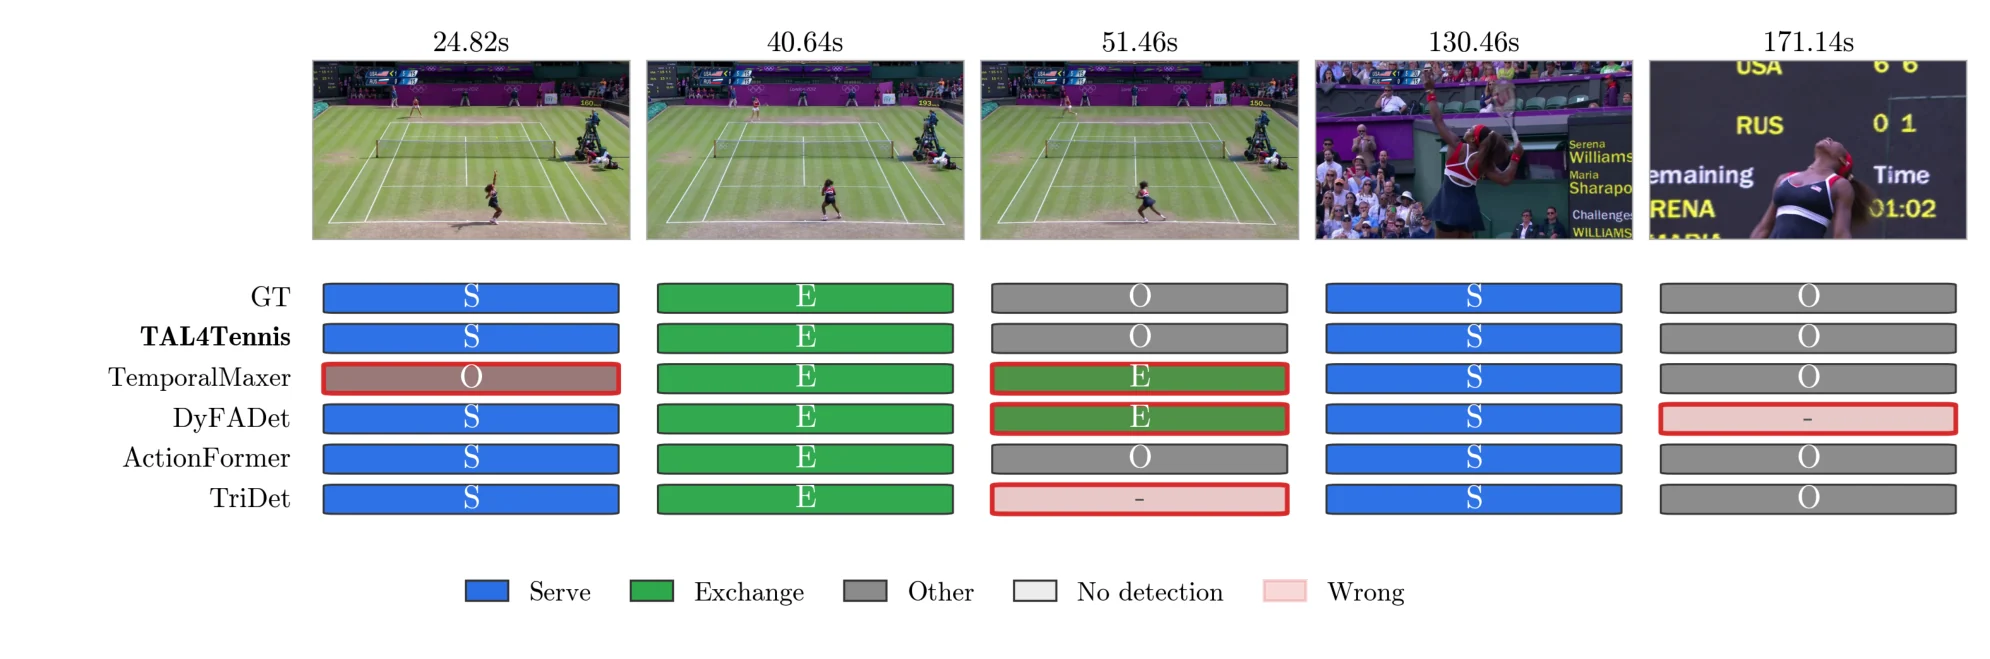
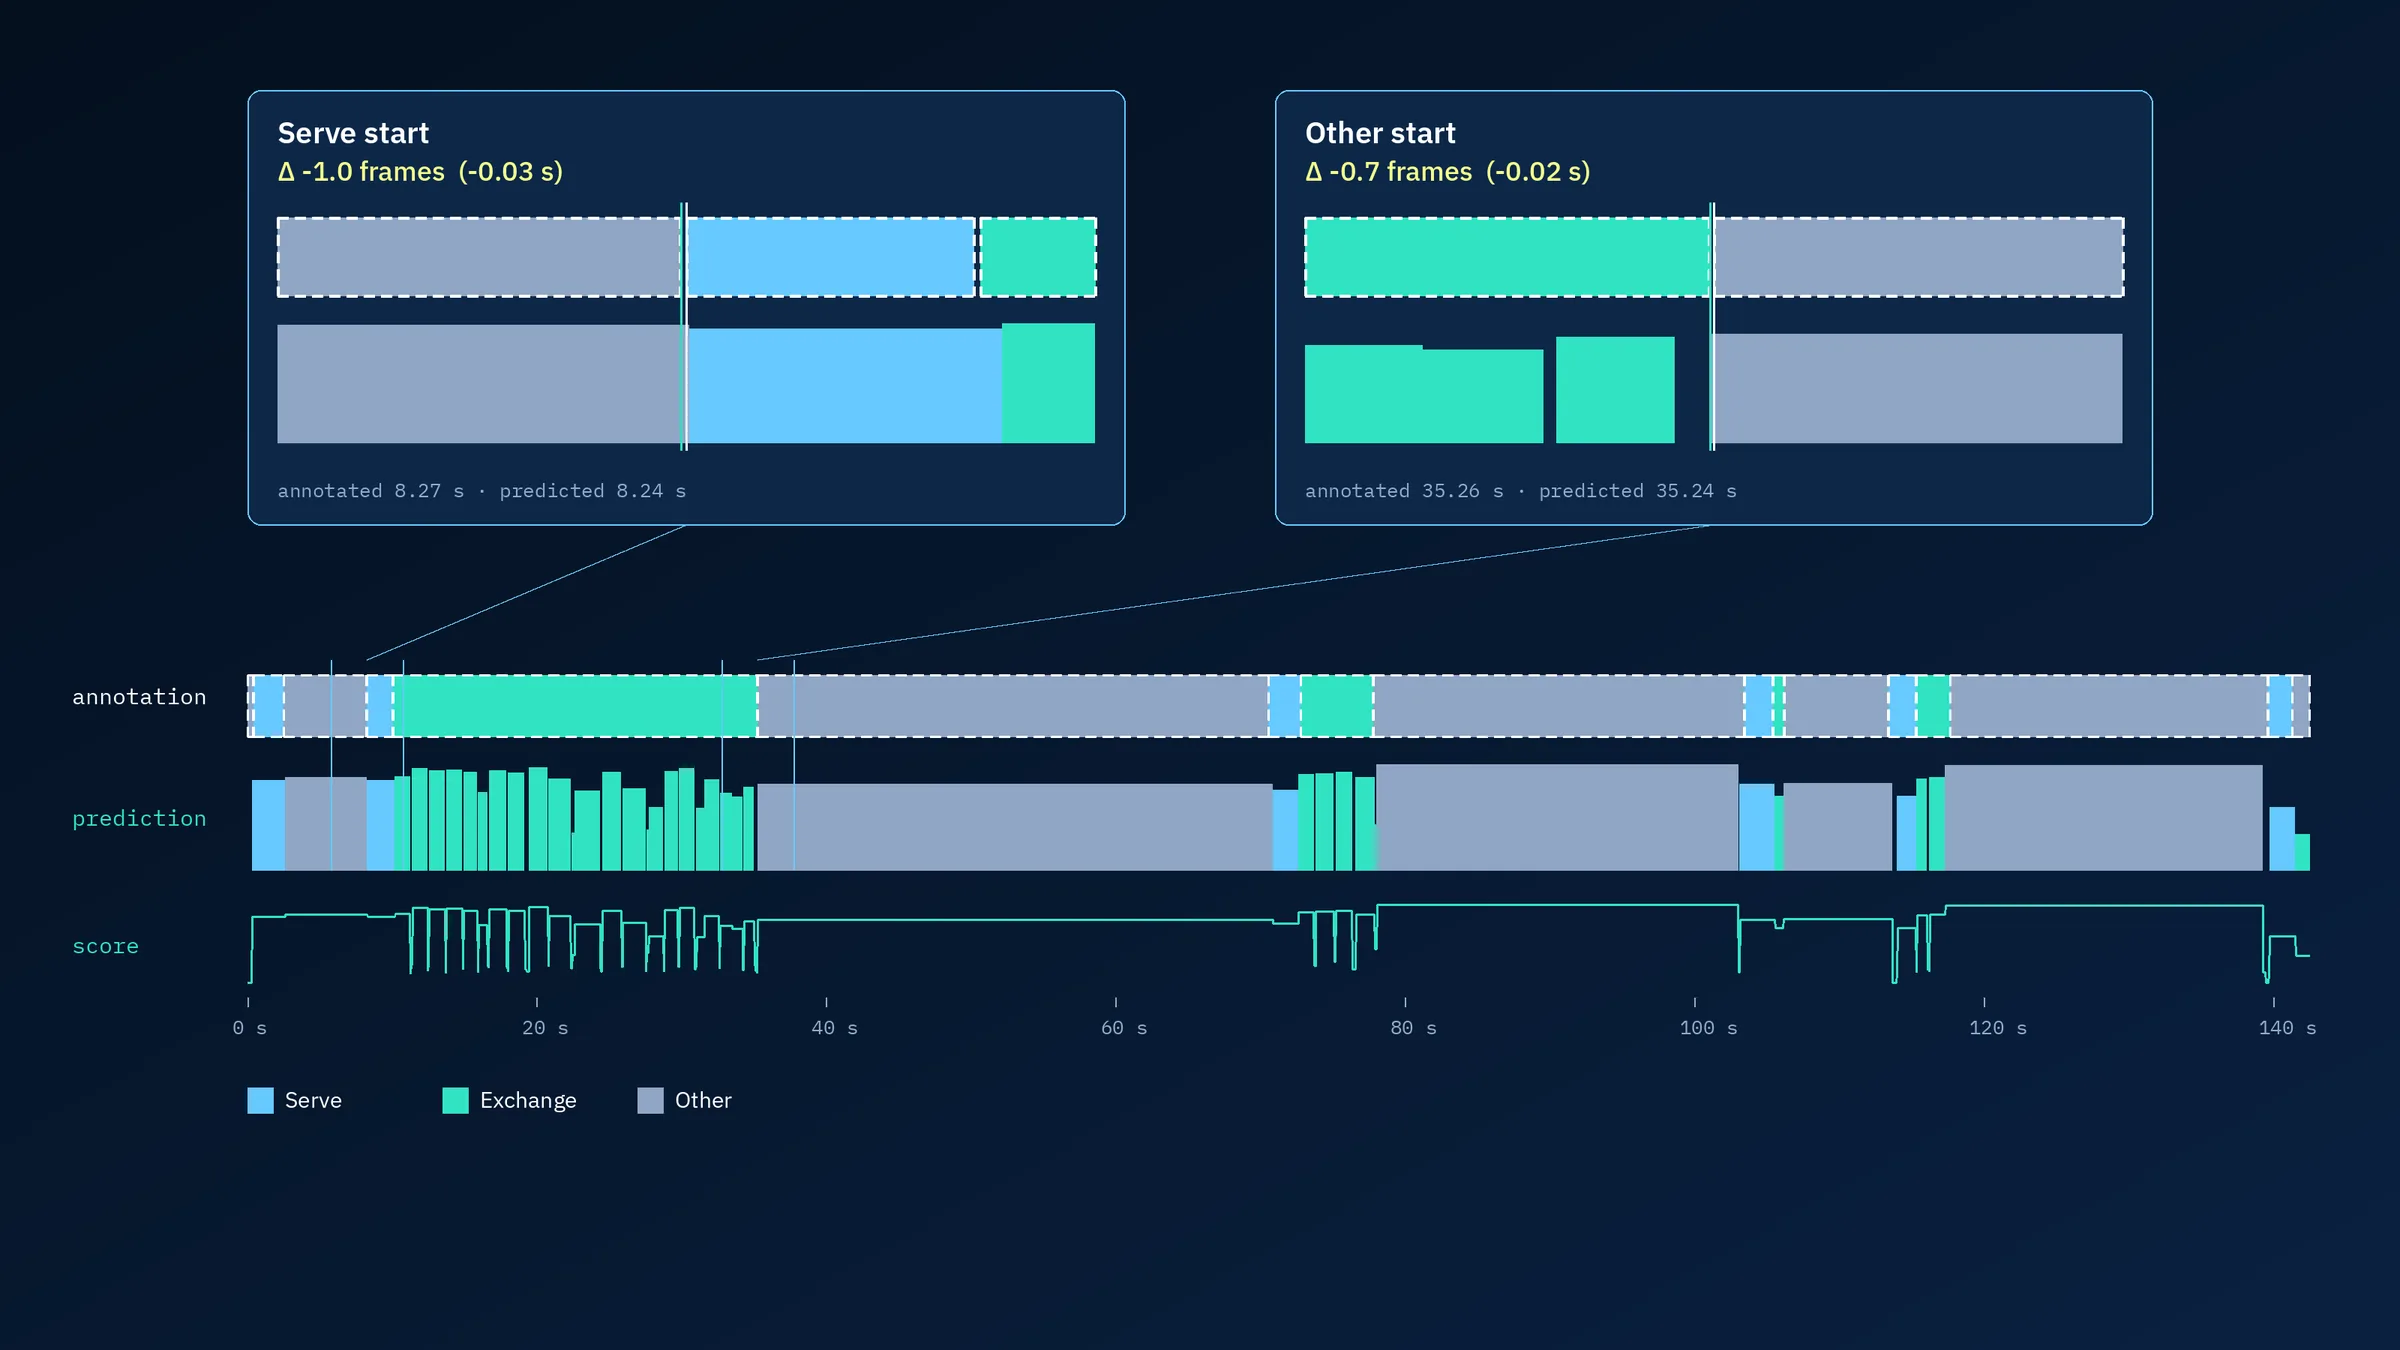
Demo
Limits and next steps
The video encoder stays frozen and is never adapted to the localisation objective, which bounds fine-grained event recognition (event F1 of 8.51 at F³Set's finest vocabulary). Longer temporal context helps, but not uniformly across thresholds.
Beyond this project
Phase and event detection in any long untrimmed stream: highlight generation, video monitoring, process and procedure analysis.
Research output
Paper
TAL4Tennis: Temporal Action Localization in Tennis Videos Using State Space Models
Ahmed Jouini, Mohamed Ali Lajnef, Faten Chaieb-Chakchouk, Alex Loth
ICAART 2025, SciTePress, pp. 398–406
Peer-reviewed core idea; the evaluation shown here is the thesis version.
Contact
Interested in the work?
I'm looking for AI research engineer roles in computer vision and video understanding, ideally in sports analytics, though not only. Ready to start a new journey.
Paris, France